Hourly bike rental forecast using the weather
We forecast hourly bike rentals 7 days (168 hours) ahead from a public dataset. In testing on past data, the selected method (the AI forecasting model with extra inputs) was off by 28.6% of actual volume on average, 54% less error than repeating the same hour the day before.
The request
"Forecast hourly bike rentals for the next 7 days using the weather forecast, split by casual vs. registered riders, so we know where to rebalance and when to schedule maintenance."
The forecast
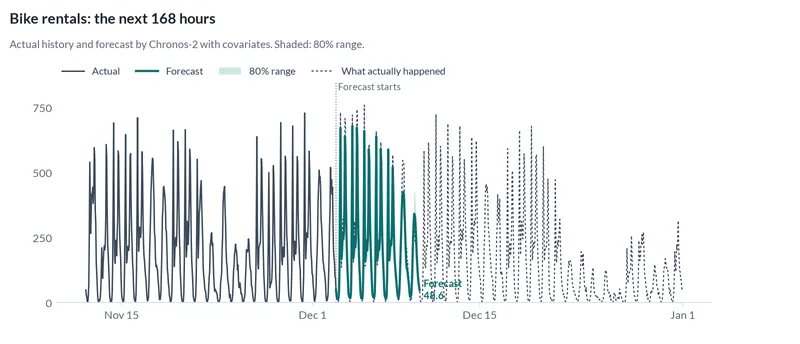
We expect about 35,590 bike rentals over the next 168 hours, about 212 per hour on average.
How accurate was it?
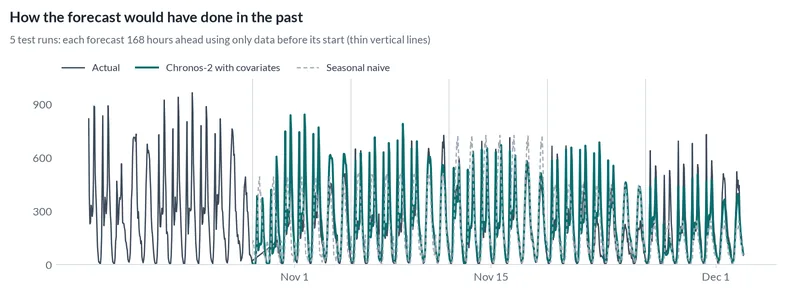
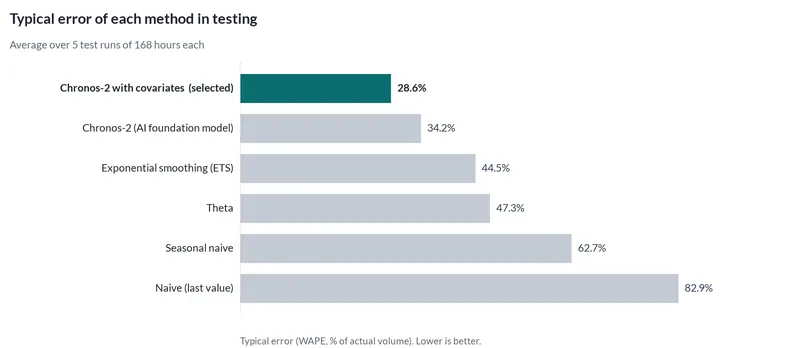
We hid the most recent stretch of history, forecast it using only what came before, and compared with what really happened. We did that 5 times, each time 7 days (168 hours) ahead, for every method below. The typical error is the share of actual volume the forecast missed by.
The selected method, the AI forecasting model, also given temperature, feels-like temperature, humidity, wind speed, weather conditions, holidays and working days as extra inputs, was off by 28.6% on average, against 62.7% for simply repeating the same hour the day before.
| Method | Kind | Typical error | Actual inside 80% range |
|---|---|---|---|
| AI model with extra inputs Selected | AI | 28.6% | 68% |
| AI forecasting model | AI | 34.2% | 59% |
| Exponential smoothing | Classic | 44.5% | 53% |
| Theta method | Classic | 47.3% | 100% |
| Repeat last season | Simple rule | 62.7% | 88% |
| Repeat the last value | Simple rule | 82.9% | 100% |
Reality check on data no model saw
Before running anything, we set aside the final 168 hours of the data (from 2012-12-02). Nothing in the testing above or the method choice could see them. Here is how every method did on that stretch.
The selected method was the most accurate here too, with 13.3% error.
| Method | Typical error |
|---|---|
| AI model with extra inputs Selected | 13.3% |
| AI forecasting model | 16.9% |
| Theta method | 33.4% |
| Exponential smoothing | 33.7% |
| Repeat last season | 58.9% |
| Repeat the last value | 83.9% |
What the engine noticed in the data
- Forecast made as of Dec 02, 2012: 694 later rows were hidden from the models and used afterwards to check the forecast.
Technical details
- Data
- Bike Sharing Dataset (UCI ML Repository #275; Capital Bikeshare, Washington DC). 1 series, hourly, from 2011-01-01 to 2012-12-02.
- How we prepared the data
- Hourly total rentals (cnt). The data ends in Dec 2012, so the forecast is made as of Dec 2, 2012 and checked against the following week. Weather for that week is taken from the actual records, which stands in for a perfect weather forecast, so the 'with covariates' result is optimistic. The request also asks for casual vs. registered riders; those columns add up to the total, so they are not used as inputs (the engine would remove them anyway).
- Testing
- 5 rolling tests, each 7 days (168 hours) ahead. Selection metric: WAPE (weighted absolute percentage error, the "typical error" above). Also reported: MASE 0.92 for the selected method.
- Methods
- Chronos-2 with covariates, Chronos-2 (AI foundation model), Exponential smoothing (ETS), Theta, Seasonal naive, Naive (last value).
- Reproduce
- The case folder, spec and outputs are in the 4castPlannr repository under
cases/uci-bike-sharing/.
Data source and license
Fanaee-T, H. & Gama, J. (2013). Event labeling combining ensemble detectors and background knowledge. Progress in AI, doi:10.1007/s13748-013-0040-3. Data: UCI ML Repository, https://doi.org/10.24432/C5W894, CC BY 4.0. Raw trip data: Capital Bikeshare.
License: CC BY 4.0. Source: original data. The forecasts and charts on this page are derived from that data and carry the same attribution.
Have a decision like this?
This case is an example of staffing plans for call centers and service businesses. Send us your own export and question, and we will run the same tests on your data.
Related case studies
-
Contact center staffing plan
San Francisco 311 public data: daily phone, web and app requests forecast six weeks ahead, and an agent shift plan replayed on the weeks that followed.
San Francisco, United States · 9.8% error · 27% better than repeating last season
-
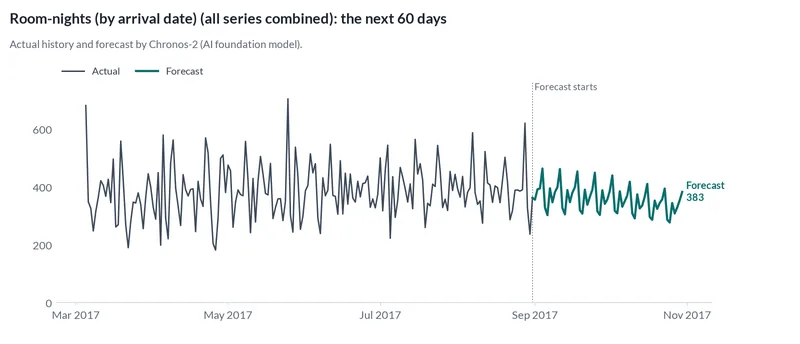
Hotel room-nights
A public dataset from two hotels: daily room-nights forecast 60 days ahead per hotel, with the accuracy we measured in testing.
Portugal · 29.6% error · 37% better than repeating last season
-
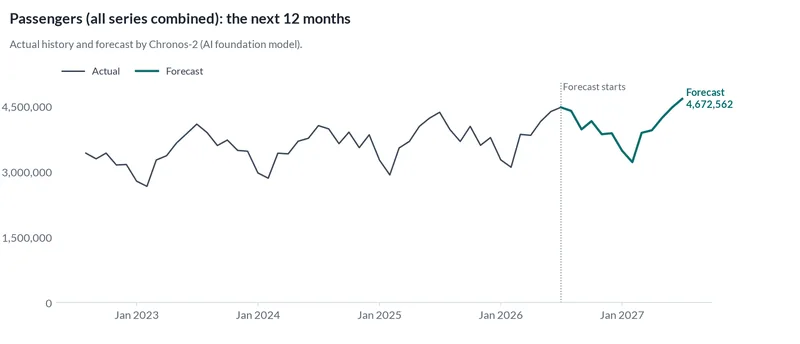
Airport passengers by airline
San Francisco International Airport's public statistics: monthly passengers for the 10 largest airlines forecast a year ahead.
San Francisco, United States · 11.8% error · 38% better than repeating last season